Exploring block-sparse attention on an integrated GPU, from early failures to a faster Vulkan prefill implementation.
Research
AI tools
Exploring block-sparse attention on an integrated GPU, from early failures to a faster Vulkan prefill implementation.
Exploring block-sparse attention on an integrated GPU, from early failures to a faster Vulkan prefill implementation.
Specification
- Language
- Python
- Created
- 2026-09-10
- Repository
- leonardoeloy / moba-qwen3-4b
Release notes
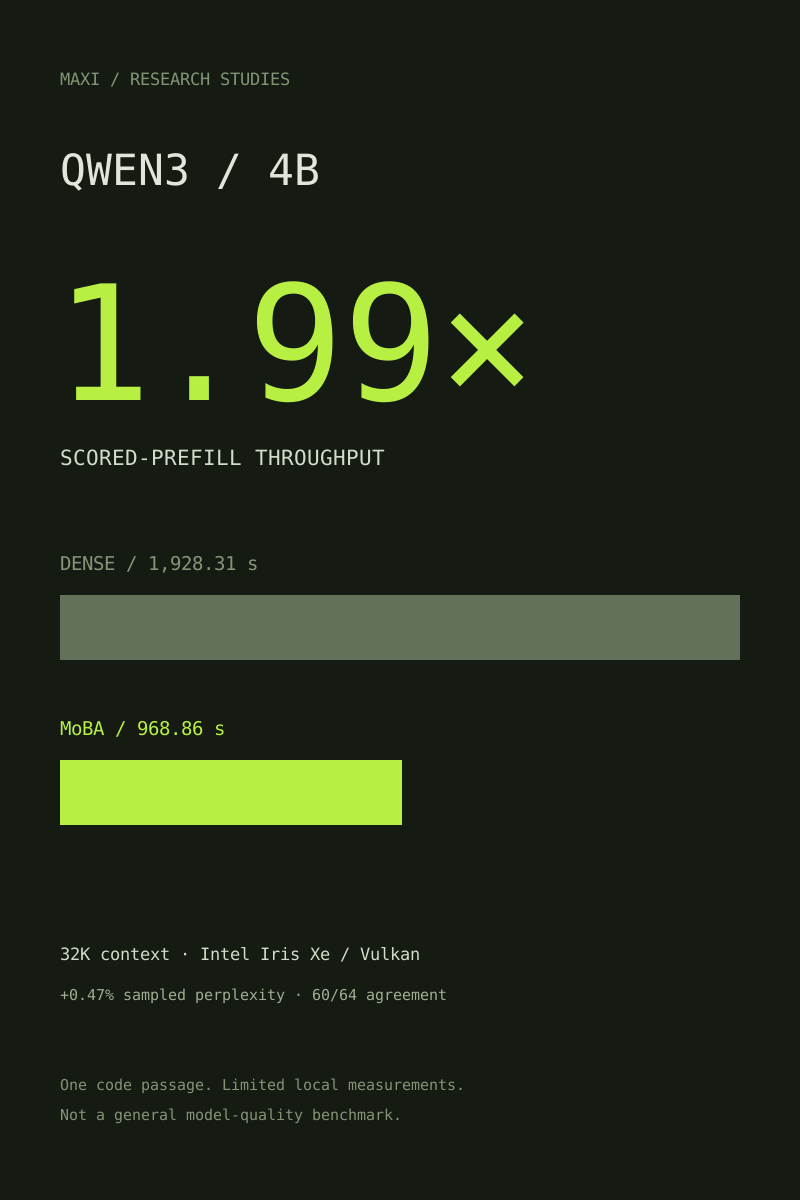
32K scored-prefill: 1,928.31 s dense versus 968.86 s compact MoBA. Sampled perplexity rose 0.47%; continuation matched 60/64 dense predictions. One local code passage; no demonstrated decode speedup.